Harnessing the Power of Gemini Audio for Real-Time Voice Applications
In a groundbreaking move to enhance conversational technology, Google has unveiled new Gemini Audio models, designed specifically for developers looking to create intelligent voice-first applications. With the introduction of Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, the Gemini API and Google AI Studio are now equipped with advanced tools that elevate real-time voice interactions.
Revolutionizing Speech-to-Speech Capabilities
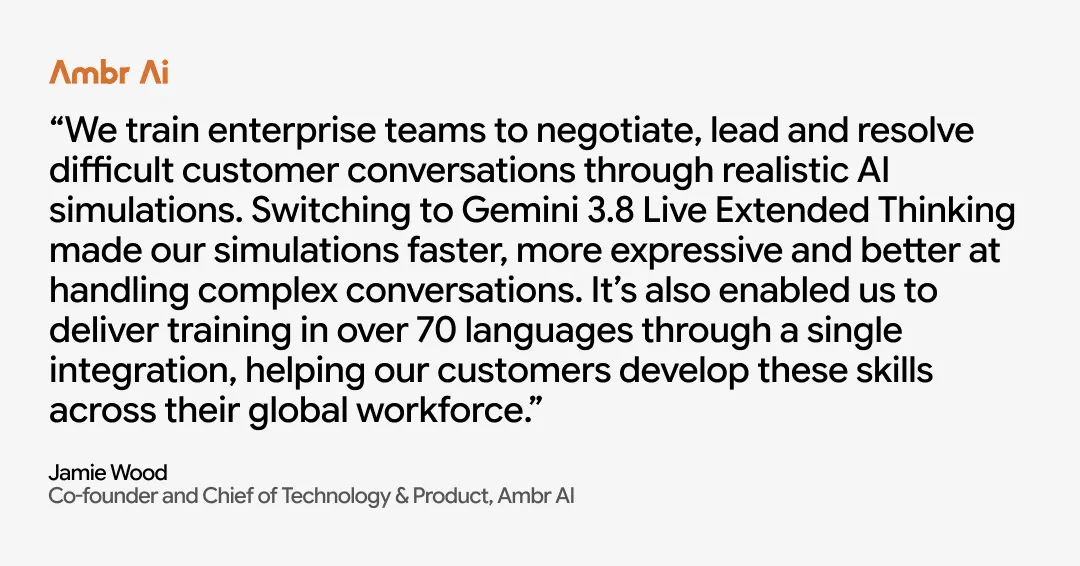
The Gemini 3.8 Live model marks a significant advancement in native speech-to-speech technology. This model is engineered to manage dialogue while executing tasks, making it ideal for developing interactive voice agents. For scenarios requiring more complex reasoning, the Gemini 3.8 Live Extended Thinking model excels, boasting the top rank on Artificial Analysis’s Speech-to-Speech leaderboard. This capability allows for deeper reasoning processes, enabling applications to handle intricate requests seamlessly.
Enhanced Transcription with Gemini 3.5
Alongside the new live models, Google also released Gemini 3.5 Transcribe, a dedicated speech-to-text solution that excels in transcription accuracy across more than 85 languages. Achieving an impressive average Word Error Rate (WER) of just 4.0% in streaming mode and 2.6% in non-streaming mode, this model is a game changer for developers focusing on real-time audio applications. Its precision makes it suitable for various use cases, from captioning to call center support.
Key Features of Gemini Audio Models
- Interactive Dialogue Management: Gemini 3.8 Live allows for continuous dialogue while executing tasks.
- Complex Reasoning: The Extended Thinking feature supports multi-step reasoning, enhancing conversational flow.
- High Precision Transcription: Gemini 3.5 Transcribe provides accurate speech-to-text capabilities, ideal for diverse applications.
- Multi-Language Support: With coverage of over 85 languages, developers can reach a global audience.
Integrating with Leading Platforms
Developers can leverage these models through the Live API, available at a competitive rate of $0.005 per minute for audio input and $0.018 per minute for audio output. This pricing structure facilitates the scaling of voice applications without compromising on performance. Additionally, the models can be accessed through various integration partners, including Agora, Fishjam, LiveKit, LangChain, Pipecat, Vercel, and Vision Agents, which provide essential media streaming infrastructure for real-world deployment.
Getting Started with Gemini Audio
To begin utilizing these powerful tools, developers can explore the models at ai.studio/live, clone example applications from GitHub, or enhance their agents using the live API skills. Furthermore, the Gemini API offers additional capabilities for creating audio experiences through speech and music generation models, broadening the scope of what can be achieved in voice technology.
As Google continues to innovate in the realm of voice applications, the introduction of the Gemini Audio models represents a significant advancement. Developers are encouraged to dive into these resources and explore the potential of real-time voice applications. The future of conversational AI is here, and it’s time to start building.
Source for the original facts: Original source.